Monitoring and alerting
Design and run a monitoring system for a website or web app.
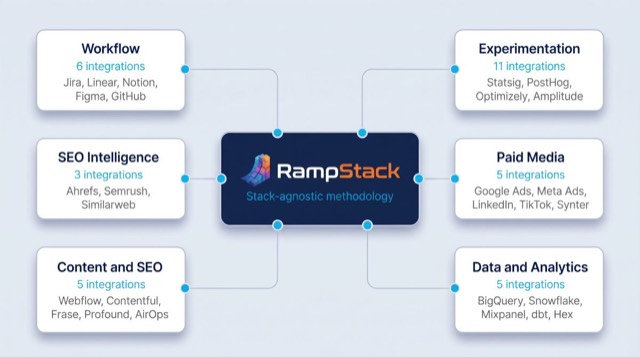
From the rampstackco/claude-skills README — shows the whole collection, not only this skill. · view on GitHub
How to use it
Claude Code
- Run the line below. It pulls the whole folder into
~/.claude/skills/monitoring-and-alerting. - Describe your job in plain words. Claude Code follows the skill from there.
npx degit rampstackco/claude-skills/skills/monitoring-and-alerting#main ~/.claude/skills/monitoring-and-alertingFor one project only, change the path to .claude/skills/monitoring-and-alerting.
Claude (web or desktop app)
- On this page open ⋯ → Download .md.
- Save it as SKILL.md in a folder, zip the folder, then Customize → Skills → + → Create skill → Upload a skill.
- Pick the file and Save. Claude shows the name and description and runs a security scan.
- Check the skill is switched on.
- Start a new chat and describe your job in plain words. The AI follows the skill from there.
ChatGPT or another app
- ChatGPT: make a Project and paste it into Instructions.
- Neither? Paste it at the top of a new chat — it works for that chat.
Not working?
- Check which app you pasted it into — the steps above name the right one.
- Some skills need the paid tier of Claude or ChatGPT.
Paste into Claude, ChatGPT or Cursor.
Source of Monitoring and alerting
Show the full text263 lines
| name | description | category | catalog_summary | display_order |
|---|---|---|---|---|
| monitoring-and-alerting | Design and run a monitoring system for a website or web app. Use this skill when setting up uptime checks, defining SLOs, configuring error tracking, choosing what to alert on, designing on-call rotations, or fixing alert fatigue. Triggers on monitoring, alerts, uptime, SLO, SLA, error rate, on-call, pager, alert fatigue, observability, dashboards, what should we monitor. Also triggers when an incident reveals a gap in monitoring. | operations | SLO design, uptime checks, alert routing, on-call rotations | 5 |
Monitoring and Alerting
Decide what to watch, what to alert on, and how to make sure the right person finds out when things break.
When to use
- Setting up monitoring on a new site or service
- Defining SLOs (service level objectives) and error budgets
- Choosing which alerts page someone vs which go to a quiet channel
- Designing or fixing on-call rotation
- Diagnosing alert fatigue
- Filling monitoring gaps revealed by an incident
- Migrating monitoring vendors
When NOT to use
- Responding to an active incident (use
incident-response) - Writing the post-mortem (use
after-action-report) - Designing analytics dashboards for product metrics (use
analytics-strategy) - Performance optimization itself (use
performance-optimization)
Required inputs
- The system you're monitoring (URLs, services, dependencies)
- Existing monitoring tools (uptime, errors, logs, APM)
- Business hours and team timezone(s)
- Who is on-call or available for incidents
- Existing SLOs or success metrics, if any
The framework: 4 layers
Monitoring works in layers. Skip a layer and you'll miss a class of problems.
Layer 1: Availability
Is the site up? The simplest, most important layer.
- HTTP checks from multiple regions (every 1-5 minutes)
- DNS resolution checks
- Certificate expiration checks
- Status code checks (alert on 5xx, not just timeout)
Threshold: any sustained downtime (more than 2 consecutive failed checks) pages.
Layer 2: Correctness
The site is up, but is it serving the right thing?
- Synthetic checks (a script that loads the homepage, clicks a button, validates expected text)
- Critical user journeys (signup, checkout, search)
- Content presence checks (homepage hasn't gone blank)
- API contract checks (response shape and key fields are present)
Threshold: failures of critical-path synthetics page. Non-critical page-level synthetics alert during business hours only.
Layer 3: Performance
The site is up and correct, but is it fast enough?
- Core Web Vitals (LCP, INP, CLS) from real users (RUM)
- Synthetic performance (Lighthouse, WebPageTest, custom)
- API response times (p50, p95, p99)
- Database query times for slow queries
- Dependency response times (third-party APIs)
Threshold: regressions from baseline (e.g., p95 doubled in 5 minutes). Don't alert on absolute thresholds without baselines.
Layer 4: Errors and anomalies
The site is up, correct, and fast for most, but errors are happening.
- Error rate (% of requests returning 5xx)
- Client-side error rate (uncaught JS exceptions)
- Log error volume (unexpected spikes)
- Anomaly detection (traffic falling off a cliff)
- Background job failures
- Queue depth
Threshold: rate-based, not count-based. "Error rate above 1% for 5 minutes" beats "more than 100 errors per minute."
SLOs and error budgets
A Service Level Objective is the target for reliability. Common form: "99.9% of homepage requests succeed in under 2 seconds, measured over 30 days."
The components:
- The thing you're measuring (homepage requests)
- The success criterion (returns 2xx in under 2 seconds)
- The target (99.9% of them)
- The window (over 30 days)
The error budget is the inverse: 0.1% of requests can fail. If you've used the whole budget, slow down on risky changes.
Picking SLOs
Don't aim for 100%. Don't aim for "five nines" (99.999%) unless you really need it. Each nine costs an order of magnitude more.
| SLO | Allowed downtime per month |
|---|---|
| 99% | 7 hours, 18 minutes |
| 99.9% | 43 minutes |
| 99.95% | 21 minutes |
| 99.99% | 4 minutes, 22 seconds |
| 99.999% | 26 seconds |
For most marketing sites, 99.9% is plenty. For SaaS, 99.95% is reasonable. Anything higher needs significant infrastructure investment.
Using error budgets
When the budget is healthy, ship aggressively. When the budget is half-spent, slow down. When the budget is exhausted, freeze risky changes until reliability recovers.
This is what makes SLOs useful: they create a feedback loop between reliability and velocity.
Workflow
Step 1: Inventory what's already monitored
What tools are in place? What checks exist? What dashboards? What alerts?
Many teams have a tangle of half-configured tools. The first job is the inventory.
Step 2: Map the system
Draw the architecture. Front-end, back-end, database, third-party APIs, queues, workers. Each box is a candidate for monitoring.
For each box, ask:
- What does "up" mean?
- What does "correct" mean?
- What does "fast" mean?
- What's the most common failure mode?
Step 3: Define the SLOs
Pick 3-5 SLOs. They should be:
- Tied to user-visible behavior (not internal metrics)
- Achievable with current infrastructure
- Measured automatically
- Reviewed at least quarterly
Step 4: Set up checks across the 4 layers
For each box, configure checks at each layer. Some boxes won't have all four; that's fine.
| Box | Availability | Correctness | Performance | Errors |
|---|---|---|---|---|
| Homepage | HTTP check | Synthetic | LCP/INP | JS errors |
| Login API | HTTP check | Synthetic flow | p95 latency | 5xx rate |
Step 5: Decide what pages and what doesn't
Three tiers:
- Page (wakes someone up): site down, critical flow broken, error rate spike, security incident.
- Notify (during business hours): non-critical synthetic failure, performance regression, slow query, dependency degradation.
- Log (no notification): anomalies for later review, low-priority warnings, info-level events.
Anything in tier 1 must be:
- Actionable (the on-call can do something about it)
- Important (it represents real impact)
- Rare (less than 1-2 per week is the goal)
If tier 1 alerts fire frequently, alert fatigue sets in. People stop responding.
Step 6: Configure routing
Where do alerts go?
- Tier 1: paging system (e.g., PagerDuty). Do not onboard onto Opsgenie: Atlassian ended sales in June 2025 and support ends April 2027. Direct to on-call.
- Tier 2: chat channel (Slack, Teams). Tagged with the area.
- Tier 3: dashboard or log only.
Each tier should have a documented escalation path. If the on-call doesn't ack within 5-15 minutes, escalate.
Step 7: Build dashboards
One dashboard per audience:
- Real-time ops dashboard: current health, recent alerts, error rates, throughput
- SLO dashboard: SLO status and error budget consumption
- Per-service dashboards: detail for individual services or pages
- Executive dashboard: uptime over weeks/months, key business metrics
Dashboards are different from alerts. Alerts say "look now." Dashboards say "here's what's happening."
Step 8: Run an alert audit
Every quarter, audit:
- Which alerts fired? Were they actionable?
- Which alerts didn't fire when they should have?
- Are any alerts noisy (more than once a week, low actionability)?
- Are runbooks up to date?
- Have SLOs been met? Any consistently breached?
Tune the system. Monitoring drifts without active maintenance.
Failure patterns
Alert on cause, not symptom. "CPU is high" is a cause. "Users are slow" is a symptom. Alert on symptoms; investigate causes.
Alert without a runbook. If the on-call doesn't know what to do, the alert is useless. Every paging alert needs a runbook (even a one-line one).
No baselines for "normal." Alerting on "more than 100 errors per minute" sounds reasonable but a busy day might exceed that without anything being wrong. Use rate-based and anomaly-based alerts.
Single-region monitoring. Your monitoring service in the same region as your site means you'll miss regional outages and you'll get woken up when monitoring itself has issues.
Monitoring the monitoring. Or rather, not. If your alerting platform is down, who tells you? Most paging services offer their own status feeds. Subscribe.
Too many tiers of severity. P0/P1/P2/P3/P4 with different SLAs becomes a sorting exercise. Three tiers (page, notify, log) is plenty.
Synthetics that don't match reality. A synthetic that hits the homepage every minute tests "is the homepage up." It doesn't test "is the actual user flow working." Build synthetics for the journeys that matter.
Static thresholds that never get tuned. Traffic grows, behavior changes, thresholds set last year are wrong. Review thresholds quarterly.
On-call rotation with no handoffs. Each new on-call has to figure out the system. Document. Run weekly handoff meetings or async updates.
Pager fatigue. If on-call is paged more than once or twice a week, something is wrong. Audit the alerts. Reduce, tune, or fix the underlying issues.
Output format
A monitoring plan includes:
- System map: what's being monitored
- SLOs: the 3-5 reliability targets
- Checks per layer: availability, correctness, performance, errors
- Alert tiering: what pages, what notifies, what logs
- Routing: where alerts go, escalation paths
- Dashboards: what audiences see
- Runbooks: linked from each paging alert
- Audit cadence: when this gets reviewed
If required data is unavailable
This skill's output depends on data, measurements, or tool results it cannot generate on its own. When a required input, tool, or data source is unavailable or unverifiable, the sanctioned output is the deliverable with the gap stated: what was needed, what was actually obtained or verified, and which parts of the output are affected. Fabricating, estimating, or interpolating a required number to complete the deliverable is never sanctioned. A stated gap is a complete answer.
Reference files
references/slo-design-guide.md: Detailed walkthrough of writing SLOs, error budget policies, and common SLO mistakes for web services.
| 1 | |
| 2 | name monitoring-and-alerting |
| 3 | description "Design and run a monitoring system for a website or web app. Use this skill when setting up uptime checks, defining SLOs, configuring error tracking, choosing what to alert on, designing on-call rotations, or fixing alert fatigue. Triggers on monitoring, alerts, uptime, SLO, SLA, error rate, on-call, pager, alert fatigue, observability, dashboards, what should we monitor. Also triggers when an incident reveals a gap in monitoring." |
| 4 | category operations |
| 5 | catalog_summary "SLO design, uptime checks, alert routing, on-call rotations" |
| 6 | display_order 5 |
| 7 | |
| 8 | |
| 9 | # Monitoring and Alerting |
| 10 | |
| 11 | Decide what to watch, what to alert on, and how to make sure the right person finds out when things break. |
| 12 | |
| 13 | |
| 14 | |
| 15 | ## When to use |
| 16 | |
| 17 | Setting up monitoring on a new site or service |
| 18 | Defining SLOs (service level objectives) and error budgets |
| 19 | Choosing which alerts page someone vs which go to a quiet channel |
| 20 | Designing or fixing on-call rotation |
| 21 | Diagnosing alert fatigue |
| 22 | Filling monitoring gaps revealed by an incident |
| 23 | Migrating monitoring vendors |
| 24 | |
| 25 | ## When NOT to use |
| 26 | |
| 27 | Responding to an active incident (use `incident-response`) |
| 28 | Writing the post-mortem (use `after-action-report`) |
| 29 | Designing analytics dashboards for product metrics (use `analytics-strategy`) |
| 30 | Performance optimization itself (use `performance-optimization`) |
| 31 | |
| 32 | |
| 33 | |
| 34 | ## Required inputs |
| 35 | |
| 36 | The system you're monitoring (URLs, services, dependencies) |
| 37 | Existing monitoring tools (uptime, errors, logs, APM) |
| 38 | Business hours and team timezone(s) |
| 39 | Who is on-call or available for incidents |
| 40 | Existing SLOs or success metrics, if any |
| 41 | |
| 42 | |
| 43 | |
| 44 | ## The framework: 4 layers |
| 45 | |
| 46 | Monitoring works in layers. Skip a layer and you'll miss a class of problems. |
| 47 | |
| 48 | ### Layer 1: Availability |
| 49 | |
| 50 | Is the site up? The simplest, most important layer. |
| 51 | |
| 52 | HTTP checks from multiple regions (every 1-5 minutes) |
| 53 | DNS resolution checks |
| 54 | Certificate expiration checks |
| 55 | Status code checks (alert on 5xx, not just timeout) |
| 56 | |
| 57 | Threshold: any sustained downtime (more than 2 consecutive failed checks) pages. |
| 58 | |
| 59 | ### Layer 2: Correctness |
| 60 | |
| 61 | The site is up, but is it serving the right thing? |
| 62 | |
| 63 | Synthetic checks (a script that loads the homepage, clicks a button, validates expected text) |
| 64 | Critical user journeys (signup, checkout, search) |
| 65 | Content presence checks (homepage hasn't gone blank) |
| 66 | API contract checks (response shape and key fields are present) |
| 67 | |
| 68 | Threshold: failures of critical-path synthetics page. Non-critical page-level synthetics alert during business hours only. |
| 69 | |
| 70 | ### Layer 3: Performance |
| 71 | |
| 72 | The site is up and correct, but is it fast enough? |
| 73 | |
| 74 | Core Web Vitals (LCP, INP, CLS) from real users (RUM) |
| 75 | Synthetic performance (Lighthouse, WebPageTest, custom) |
| 76 | API response times (p50, p95, p99) |
| 77 | Database query times for slow queries |
| 78 | Dependency response times (third-party APIs) |
| 79 | |
| 80 | Threshold: regressions from baseline (e.g., p95 doubled in 5 minutes). Don't alert on absolute thresholds without baselines. |
| 81 | |
| 82 | ### Layer 4: Errors and anomalies |
| 83 | |
| 84 | The site is up, correct, and fast for most, but errors are happening. |
| 85 | |
| 86 | Error rate (% of requests returning 5xx) |
| 87 | Client-side error rate (uncaught JS exceptions) |
| 88 | Log error volume (unexpected spikes) |
| 89 | Anomaly detection (traffic falling off a cliff) |
| 90 | Background job failures |
| 91 | Queue depth |
| 92 | |
| 93 | Threshold: rate-based, not count-based. "Error rate above 1% for 5 minutes" beats "more than 100 errors per minute." |
| 94 | |
| 95 | |
| 96 | |
| 97 | ## SLOs and error budgets |
| 98 | |
| 99 | A Service Level Objective is the target for reliability. Common form: "99.9% of homepage requests succeed in under 2 seconds, measured over 30 days." |
| 100 | |
| 101 | The components: |
| 102 | **The thing you're measuring** (homepage requests) |
| 103 | **The success criterion** (returns 2xx in under 2 seconds) |
| 104 | **The target** (99.9% of them) |
| 105 | **The window** (over 30 days) |
| 106 | |
| 107 | The error budget is the inverse: 0.1% of requests can fail. If you've used the whole budget, slow down on risky changes. |
| 108 | |
| 109 | ### Picking SLOs |
| 110 | |
| 111 | Don't aim for 100%. Don't aim for "five nines" (99.999%) unless you really need it. Each nine costs an order of magnitude more. |
| 112 | |
| 113 | | SLO | Allowed downtime per month | |
| 114 | |---|---| |
| 115 | | 99% | 7 hours, 18 minutes | |
| 116 | | 99.9% | 43 minutes | |
| 117 | | 99.95% | 21 minutes | |
| 118 | | 99.99% | 4 minutes, 22 seconds | |
| 119 | | 99.999% | 26 seconds | |
| 120 | |
| 121 | For most marketing sites, 99.9% is plenty. For SaaS, 99.95% is reasonable. Anything higher needs significant infrastructure investment. |
| 122 | |
| 123 | ### Using error budgets |
| 124 | |
| 125 | When the budget is healthy, ship aggressively. When the budget is half-spent, slow down. When the budget is exhausted, freeze risky changes until reliability recovers. |
| 126 | |
| 127 | This is what makes SLOs useful: they create a feedback loop between reliability and velocity. |
| 128 | |
| 129 | |
| 130 | |
| 131 | ## Workflow |
| 132 | |
| 133 | ### Step 1: Inventory what's already monitored |
| 134 | |
| 135 | What tools are in place? What checks exist? What dashboards? What alerts? |
| 136 | |
| 137 | Many teams have a tangle of half-configured tools. The first job is the inventory. |
| 138 | |
| 139 | ### Step 2: Map the system |
| 140 | |
| 141 | Draw the architecture. Front-end, back-end, database, third-party APIs, queues, workers. Each box is a candidate for monitoring. |
| 142 | |
| 143 | For each box, ask: |
| 144 | What does "up" mean? |
| 145 | What does "correct" mean? |
| 146 | What does "fast" mean? |
| 147 | What's the most common failure mode? |
| 148 | |
| 149 | ### Step 3: Define the SLOs |
| 150 | |
| 151 | Pick 3-5 SLOs. They should be: |
| 152 | Tied to user-visible behavior (not internal metrics) |
| 153 | Achievable with current infrastructure |
| 154 | Measured automatically |
| 155 | Reviewed at least quarterly |
| 156 | |
| 157 | ### Step 4: Set up checks across the 4 layers |
| 158 | |
| 159 | For each box, configure checks at each layer. Some boxes won't have all four; that's fine. |
| 160 | |
| 161 | | Box | Availability | Correctness | Performance | Errors | |
| 162 | |---|---|---|---|---| |
| 163 | | Homepage | HTTP check | Synthetic | LCP/INP | JS errors | |
| 164 | | Login API | HTTP check | Synthetic flow | p95 latency | 5xx rate | |
| 165 | |
| 166 | ### Step 5: Decide what pages and what doesn't |
| 167 | |
| 168 | Three tiers: |
| 169 | |
| 170 | **Page (wakes someone up):** site down, critical flow broken, error rate spike, security incident. |
| 171 | **Notify (during business hours):** non-critical synthetic failure, performance regression, slow query, dependency degradation. |
| 172 | **Log (no notification):** anomalies for later review, low-priority warnings, info-level events. |
| 173 | |
| 174 | Anything in tier 1 must be: |
| 175 | Actionable (the on-call can do something about it) |
| 176 | Important (it represents real impact) |
| 177 | Rare (less than 1-2 per week is the goal) |
| 178 | |
| 179 | If tier 1 alerts fire frequently, alert fatigue sets in. People stop responding. |
| 180 | |
| 181 | ### Step 6: Configure routing |
| 182 | |
| 183 | Where do alerts go? |
| 184 | |
| 185 | Tier 1: paging system (e.g., PagerDuty). Do not onboard onto Opsgenie: Atlassian ended sales in June 2025 and support ends April 2027. Direct to on-call. |
| 186 | Tier 2: chat channel (Slack, Teams). Tagged with the area. |
| 187 | Tier 3: dashboard or log only. |
| 188 | |
| 189 | Each tier should have a documented escalation path. If the on-call doesn't ack within 5-15 minutes, escalate. |
| 190 | |
| 191 | ### Step 7: Build dashboards |
| 192 | |
| 193 | One dashboard per audience: |
| 194 | |
| 195 | **Real-time ops dashboard:** current health, recent alerts, error rates, throughput |
| 196 | **SLO dashboard:** SLO status and error budget consumption |
| 197 | **Per-service dashboards:** detail for individual services or pages |
| 198 | **Executive dashboard:** uptime over weeks/months, key business metrics |
| 199 | |
| 200 | Dashboards are different from alerts. Alerts say "look now." Dashboards say "here's what's happening." |
| 201 | |
| 202 | ### Step 8: Run an alert audit |
| 203 | |
| 204 | Every quarter, audit: |
| 205 | Which alerts fired? Were they actionable? |
| 206 | Which alerts didn't fire when they should have? |
| 207 | Are any alerts noisy (more than once a week, low actionability)? |
| 208 | Are runbooks up to date? |
| 209 | Have SLOs been met? Any consistently breached? |
| 210 | |
| 211 | Tune the system. Monitoring drifts without active maintenance. |
| 212 | |
| 213 | |
| 214 | |
| 215 | ## Failure patterns |
| 216 | |
| 217 | **Alert on cause, not symptom.** "CPU is high" is a cause. "Users are slow" is a symptom. Alert on symptoms; investigate causes. |
| 218 | |
| 219 | **Alert without a runbook.** If the on-call doesn't know what to do, the alert is useless. Every paging alert needs a runbook (even a one-line one). |
| 220 | |
| 221 | **No baselines for "normal."** Alerting on "more than 100 errors per minute" sounds reasonable but a busy day might exceed that without anything being wrong. Use rate-based and anomaly-based alerts. |
| 222 | |
| 223 | **Single-region monitoring.** Your monitoring service in the same region as your site means you'll miss regional outages and you'll get woken up when monitoring itself has issues. |
| 224 | |
| 225 | **Monitoring the monitoring.** Or rather, not. If your alerting platform is down, who tells you? Most paging services offer their own status feeds. Subscribe. |
| 226 | |
| 227 | **Too many tiers of severity.** P0/P1/P2/P3/P4 with different SLAs becomes a sorting exercise. Three tiers (page, notify, log) is plenty. |
| 228 | |
| 229 | **Synthetics that don't match reality.** A synthetic that hits the homepage every minute tests "is the homepage up." It doesn't test "is the actual user flow working." Build synthetics for the journeys that matter. |
| 230 | |
| 231 | **Static thresholds that never get tuned.** Traffic grows, behavior changes, thresholds set last year are wrong. Review thresholds quarterly. |
| 232 | |
| 233 | **On-call rotation with no handoffs.** Each new on-call has to figure out the system. Document. Run weekly handoff meetings or async updates. |
| 234 | |
| 235 | **Pager fatigue.** If on-call is paged more than once or twice a week, something is wrong. Audit the alerts. Reduce, tune, or fix the underlying issues. |
| 236 | |
| 237 | |
| 238 | |
| 239 | ## Output format |
| 240 | |
| 241 | A monitoring plan includes: |
| 242 | |
| 243 | **System map:** what's being monitored |
| 244 | **SLOs:** the 3-5 reliability targets |
| 245 | **Checks per layer:** availability, correctness, performance, errors |
| 246 | **Alert tiering:** what pages, what notifies, what logs |
| 247 | **Routing:** where alerts go, escalation paths |
| 248 | **Dashboards:** what audiences see |
| 249 | **Runbooks:** linked from each paging alert |
| 250 | **Audit cadence:** when this gets reviewed |
| 251 | |
| 252 | |
| 253 | |
| 254 | ## If required data is unavailable |
| 255 | |
| 256 | This skill's output depends on data, measurements, or tool results it cannot generate on its own. When a required input, tool, or data source is unavailable or unverifiable, the sanctioned output is the deliverable with the gap stated: what was needed, what was actually obtained or verified, and which parts of the output are affected. Fabricating, estimating, or interpolating a required number to complete the deliverable is never sanctioned. A stated gap is a complete answer. |
| 257 | |
| 258 | |
| 259 | |
| 260 | ## Reference files |
| 261 | |
| 262 | [`references/slo-design-guide.md`]: Detailed walkthrough of writing SLOs, error budget policies, and common SLO mistakes for web services. |
| 263 |
Discussion
Browse more free Claude skills or everything in Development.