Take screenshots of any website using Notte browser
Website Screenshot
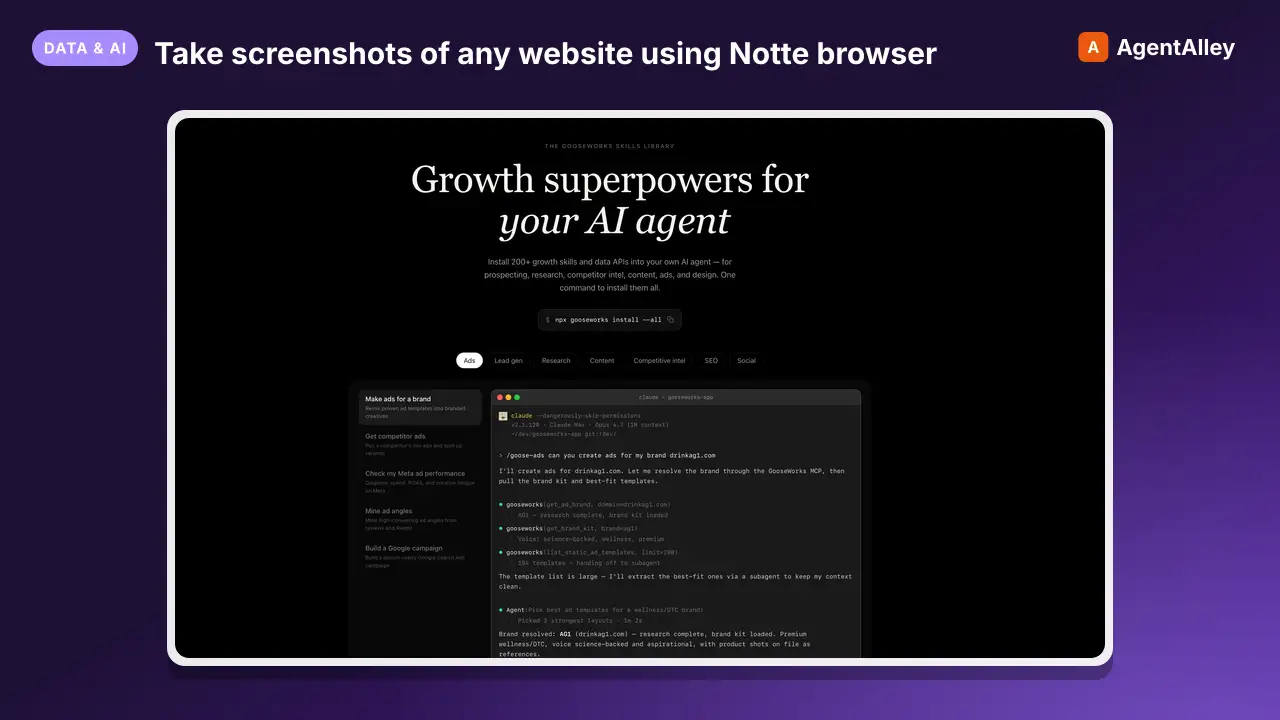
Take screenshots of any website using Notte browser automation. Use when asked to screenshot, capture, or snap a webpage.
---
name: website-screenshot-notte
description: Take screenshots of any website using Notte browser automation. Use when asked to screenshot, capture, or snap a webpage.
source: orthogonal
---


# Website Screenshot

## Setup

Read your credentials from ~/.gooseworks/credentials.json:
```bash
export GOOSEWORKS_API_KEY=$(python3 -c "import json;print(json.load(open('$HOME/.gooseworks/credentials.json'))['api_key'])")
export GOOSEWORKS_API_BASE=$(python3 -c "import json;print(json.load(open('$HOME/.gooseworks/credentials.json')).get('api_base','https://api.gooseworks.ai'))")
```

If ~/.gooseworks/credentials.json does not exist, tell the user to run: `npx gooseworks login`
Overview
If ~/.gooseworks/credentials.json does not exist, tell the user to run: npx gooseworks login
Manual install (npx, ZIP)
Claude Code
npx skills add gooseworks-ai/goose-skills --skill website-screenshot-notte -g -a claude-codeClaude Code (manual)
mkdir -p ~/.claude/skills && curl -sL https://codeload.github.com/gooseworks-ai/goose-skills/tar.gz/615c685f34f8 \
  | tar -xz -C ~/.claude/skills --strip-components=4 goose-skills-615c685f34f8/skills/research-tools/capabilities/website-screenshot-notte
Windows (PowerShell)
New-Item -ItemType Directory -Force "$HOME\.claude\skills" | Out-Null; Invoke-WebRequest "https://m.agentalley.io/zip/714f78496c9dc19af80a/website-screenshot-notte.zip" -OutFile "$env:TEMP\website-screenshot-notte.zip"; Expand-Archive "$env:TEMP\website-screenshot-notte.zip" -DestinationPath "$HOME\.claude\skills" -ForceClaude.ai / desktop
Codex, Cursor, other agents
Connects with Agent Alley MCP · agentalley.io/mcp
Files included
SKILL.md4.1 KBskill.meta.json303 B
Read the files here
gooseworks-ai/
SKILL.md
Show the full text123 lines
Website Screenshot
Setup
Read your credentials from ~/.gooseworks/credentials.json:
export GOOSEWORKS_API_KEY=$(python3 -c "import json;print(json.load(open('$HOME/.gooseworks/credentials.json'))['api_key'])")
export GOOSEWORKS_API_BASE=$(python3 -c "import json;print(json.load(open('$HOME/.gooseworks/credentials.json')).get('api_base','https://api.gooseworks.ai'))")
If ~/.gooseworks/credentials.json does not exist, tell the user to run: npx gooseworks login
All endpoints use Bearer auth: -H "Authorization: Bearer $GOOSEWORKS_API_KEY"
Take screenshots of any website URL and save them as image files.
Requirements
- Orthogonal CLI:
npm install -g @orth/cli
Workflow
Take a screenshot of a URL in 4 steps:
Step 1: Start a browser session
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/start","body":{"headless":true}}'
Save the session_id from the response.
Step 2: Navigate to the URL
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/{session_id}/page/execute","body":{"type":"goto","url":"https://example.com"}}'
Step 3: Take the screenshot
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/{session_id}/page/screenshot","body":{}}'
For a full-page screenshot:
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/{session_id}/page/screenshot","body":{"full_page":true}}'
Step 4: Stop the session
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/{session_id}/stop"}'
Full Example
# 1. Start session
SESSION=$(curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/start","body":{"headless":true}}' | python3 -c "import json,sys;d=json.load(sys.stdin);print(json.dumps(d.get('data',d)))" | python3 -c "import sys,json; print(json.load(sys.stdin)['session_id'])")

# 2. Navigate
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/$SESSION/page/execute","body":{"type":"goto","url":"https://example.com"}}'

# 3. Screenshot
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/$SESSION/page/screenshot","body":{}}'

# 4. Cleanup
curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \
  -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"api":"notte","path":"/sessions/$SESSION/stop"}'
Options
| Parameter | Description |
|---|---|
full_page |
Set to true to capture the entire scrollable page |
headless |
Set to false to see the browser window (default: true) |
viewport_width |
Custom viewport width in pixels |
viewport_height |
Custom viewport height in pixels |
Tips
- Always stop the session when done to free resources
- Sessions auto-expire after 3 minutes of idle time
- Use
-oflag to save the screenshot to a file (required for binary data) - The output file must not already exist (use a unique name or delete first)
| 1 | |
| 2 | name website-screenshot-notte |
| 3 | description Take screenshots of any website using Notte browser automation. Use when asked to screenshot, capture, or snap a webpage. |
| 4 | source orthogonal |
| 5 | |
| 6 | |
| 7 | |
| 8 | # Website Screenshot |
| 9 | |
| 10 | ## Setup |
| 11 | |
| 12 | Read your credentials from ~/.gooseworks/credentials.json: |
| 13 | |
| 14 | export GOOSEWORKS_API_KEY=$(python3 -c "import json;print(json.load(open('$HOME/.gooseworks/credentials.json'))['api_key'])") |
| 15 | export GOOSEWORKS_API_BASE=$(python3 -c "import json;print(json.load(open('$HOME/.gooseworks/credentials.json')).get('api_base','https://api.gooseworks.ai'))") |
| 16 | |
| 17 | |
| 18 | If ~/.gooseworks/credentials.json does not exist, tell the user to run: `npx gooseworks login` |
| 19 | |
| 20 | All endpoints use Bearer auth: `-H "Authorization: Bearer $GOOSEWORKS_API_KEY"` |
| 21 | |
| 22 | |
| 23 | Take screenshots of any website URL and save them as image files. |
| 24 | |
| 25 | ## Requirements |
| 26 | |
| 27 | Orthogonal CLI: `npm install -g @orth/cli` |
| 28 | |
| 29 | ## Workflow |
| 30 | |
| 31 | Take a screenshot of a URL in 4 steps: |
| 32 | |
| 33 | ### Step 1: Start a browser session |
| 34 | |
| 35 | |
| 36 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 37 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 38 | -H "Content-Type: application/json" \ |
| 39 | -d '{"api":"notte","path":"/sessions/start","body":{"headless":true}}' |
| 40 | |
| 41 | |
| 42 | Save the `session_id` from the response. |
| 43 | |
| 44 | ### Step 2: Navigate to the URL |
| 45 | |
| 46 | |
| 47 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 48 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 49 | -H "Content-Type: application/json" \ |
| 50 | -d '{"api":"notte","path":"/sessions/{session_id}/page/execute","body":{"type":"goto","url":"https://example.com"}}' |
| 51 | |
| 52 | |
| 53 | ### Step 3: Take the screenshot |
| 54 | |
| 55 | |
| 56 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 57 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 58 | -H "Content-Type: application/json" \ |
| 59 | -d '{"api":"notte","path":"/sessions/{session_id}/page/screenshot","body":{}}' |
| 60 | |
| 61 | |
| 62 | For a full-page screenshot: |
| 63 | |
| 64 | |
| 65 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 66 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 67 | -H "Content-Type: application/json" \ |
| 68 | -d '{"api":"notte","path":"/sessions/{session_id}/page/screenshot","body":{"full_page":true}}' |
| 69 | |
| 70 | |
| 71 | ### Step 4: Stop the session |
| 72 | |
| 73 | |
| 74 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 75 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 76 | -H "Content-Type: application/json" \ |
| 77 | -d '{"api":"notte","path":"/sessions/{session_id}/stop"}' |
| 78 | |
| 79 | |
| 80 | ## Full Example |
| 81 | |
| 82 | |
| 83 | # 1. Start session |
| 84 | SESSION=$(curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 85 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 86 | -H "Content-Type: application/json" \ |
| 87 | -d '{"api":"notte","path":"/sessions/start","body":{"headless":true}}' | python3 -c "import json,sys;d=json.load(sys.stdin);print(json.dumps(d.get('data',d)))" | python3 -c "import sys,json; print(json.load(sys.stdin)['session_id'])") |
| 88 | |
| 89 | # 2. Navigate |
| 90 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 91 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 92 | -H "Content-Type: application/json" \ |
| 93 | -d '{"api":"notte","path":"/sessions/$SESSION/page/execute","body":{"type":"goto","url":"https://example.com"}}' |
| 94 | |
| 95 | # 3. Screenshot |
| 96 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 97 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 98 | -H "Content-Type: application/json" \ |
| 99 | -d '{"api":"notte","path":"/sessions/$SESSION/page/screenshot","body":{}}' |
| 100 | |
| 101 | # 4. Cleanup |
| 102 | curl -s -X POST $GOOSEWORKS_API_BASE/v1/proxy/orthogonal/run \ |
| 103 | -H "Authorization: Bearer $GOOSEWORKS_API_KEY" \ |
| 104 | -H "Content-Type: application/json" \ |
| 105 | -d '{"api":"notte","path":"/sessions/$SESSION/stop"}' |
| 106 | |
| 107 | |
| 108 | ## Options |
| 109 | |
| 110 | | Parameter | Description | |
| 111 | |-----------|-------------| |
| 112 | | `full_page` | Set to `true` to capture the entire scrollable page | |
| 113 | | `headless` | Set to `false` to see the browser window (default: true) | |
| 114 | | `viewport_width` | Custom viewport width in pixels | |
| 115 | | `viewport_height` | Custom viewport height in pixels | |
| 116 | |
| 117 | ## Tips |
| 118 | |
| 119 | Always stop the session when done to free resources |
| 120 | Sessions auto-expire after 3 minutes of idle time |
| 121 | Use `-o` flag to save the screenshot to a file (required for binary data) |
| 122 | The output file must not already exist (use a unique name or delete first) |
| 123 |
Details
- Updated
- Sep 21, 2026
- License
- MIT
- Stars on the repo
- ★ 1,220
- Checked
- Source
- gooseworks-ai/goose-skills ↗
- Creator
- gooseworks-ai · 206 listings
Made with website-screenshot-notte

Website Screenshot — CleanShot 2026-07-13 at 20 16 54@2x (from the gooseworks-ai/goose-skills README)
Similar skills
See all → SkillAI crawler access analysisAI Crawler Access Analysis Skill
 zubair-trabzada/geo-seo-claude · by zubair-trabzadaAI crawler access analysis. Checks robots.txt, meta tags, and HTTP headers to determine which AI crawlers can access the site. Provides a complete access map and recommendations for maximizing AI visibility while maintaining appropriate control.★ 10.8k GitHub stars
 SkillAutomate browser tasks, scrape websites, fill formsBrowser Automation - POWERFUL
 alirezarezvani/claude-skills · by alirezarezvaniUse when the user asks to automate browser tasks, scrape websites, fill forms, capture screenshots, extract structured data from web pages, or build web automation workflows. NOT for testing — use playwright-pro for that.★ 26.3k GitHub stars
 SkillBrowser automation skill for controlling Google's NotebookLMNotebookLM — Browser Automationalirezarezvani/claude-skills · by alirezarezvaniBrowser automation skill for controlling Google's NotebookLM. Use when the user wants anything done in NotebookLM (e.g., 'open NotebookLM', 'check my [name] notebook', 'ask my notebook about X', 'add [source] to NotebookLM', 'generate a Video Overview from my notebook', 'use NotebookLM Studio'). Handles reading and querying notebooks, adding sources (URLs, text, files, YouTube links, synthesized content), generating Studio outputs (Audio/Video Overviews, Mind Maps, Reports incl. Briefing Doc/Study Guide/FAQ, Flashcards, Quiz, slide decks, infographics — discover the exact set from the live Studio panel; the UI evolves fast), and creating new notebooks. Requires browser automation environment — fails gracefully when unavailable.★ 26.3k GitHub stars
 Skill4-tier progressive web scraping that auto-escalates WebFetchBrightdata
 danielmiessler/LifeOS · by danielmiessler4-tier progressive web scraping that auto-escalates WebFetch to curl to Interceptor to Bright Data proxy for bot detection and CAPTCHAs, with single-URL and multi-page crawl modes, output as markdown. USE WHEN Bright Data, scrape URL, web scraping, bot detection, crawl site, CAPTCHA, can't access, site blocking, extract page content, scrape whole site, spider domain, convert URL to markdown, getting blocked. NOT FOR simple public content (use WebFetch directly), social platform scraping with named actors (use Apify), or real-Chrome bot bypass with logged-in sessions and zero CDP fingerprint (use Interceptor).★ 19.3k GitHub stars
 SkillScrape blog posts via RSS feeds with Apify fallbackBlog feed monitor
 gooseworks-ai/goose-skills · by gooseworks-aiScrape blog posts via RSS feeds (free, no API key) with Apify fallback for JS-heavy sites. Use when you need to monitor competitor blogs, track industry content, or aggregate blog posts by keyword.★ 1.2k GitHub stars
 SkillExtract structured data from web pages using AIExtract webpage datagooseworks-ai/goose-skills · by gooseworks-aiExtract structured data from web pages using AI★ 1.2k GitHub stars
More from gooseworks-ai
 SkillMine the highest-converting ad angles from customer reviewsAd angle minergooseworks-ai/goose-skills · by gooseworks-aiMine the highest-converting ad angles from customer reviews, Reddit complaints, support tickets, and competitor ads. Extracts actual pain language, competitor weaknesses, and outcome phrases that real buyers use. Outputs a ranked angle bank with proof quotes and recommended ad formats per angle.★ 1.2k GitHub stars
 SkillAnalyze ad campaign performance data to identify what'sAd campaign analyzergooseworks-ai/goose-skills · by gooseworks-aiAnalyze ad campaign performance data (Google, Meta, LinkedIn) to identify what's working, what's wasting budget, and specific cut/scale/test recommendations. Runs statistical analysis, funnel diagnostics, and multi-channel budget reallocation with specific dollar-amount shift recommendations and scenario modeling.★ 1.2k GitHub stars
 SkillFor paid lead-gen and participant-recruitment adsAd lead quality analyzergooseworks-ai/goose-skills · by gooseworks-aiFor paid lead-gen and participant-recruitment ads, replaces vanity CPA with true CAC per qualified lead by joining ad-platform data with downstream funnel events, surfaces tracking gaps, and classifies every creative into Scale / Keep / Investigate / Cut.★ 1.2k GitHub stars
 SkillAnalyze the message match between your ads and landing pagesAd to landing page auditorgooseworks-ai/goose-skills · by gooseworks-aiAnalyze the message match between your ads and landing pages. Checks if the promise in the ad copy carries through to the landing page headline, body, and CTA. Flags disconnects that kill conversion rates. Works with Google, Meta, and LinkedIn ads.★ 1.2k GitHub stars
 SkillCheck and improve your brand's visibility across AI searchAeogooseworks-ai/goose-skills · by gooseworks-aiCheck and improve your brand's visibility across AI search engines (ChatGPT, Perplexity, Gemini, Grok, Claude, DeepSeek). Set up tracking, run visibility analyses, audit your website for AI readability, and get actionable recommendations. Uses the npx goose-aeo@latest CLI.★ 1.2k GitHub stars
 SkillSearch Amazon products - find items, compare pricesAmazon Product Searchgooseworks-ai/goose-skills · by gooseworks-aiSearch Amazon products - find items, compare prices, read reviews★ 1.2k GitHub stars