REA skill
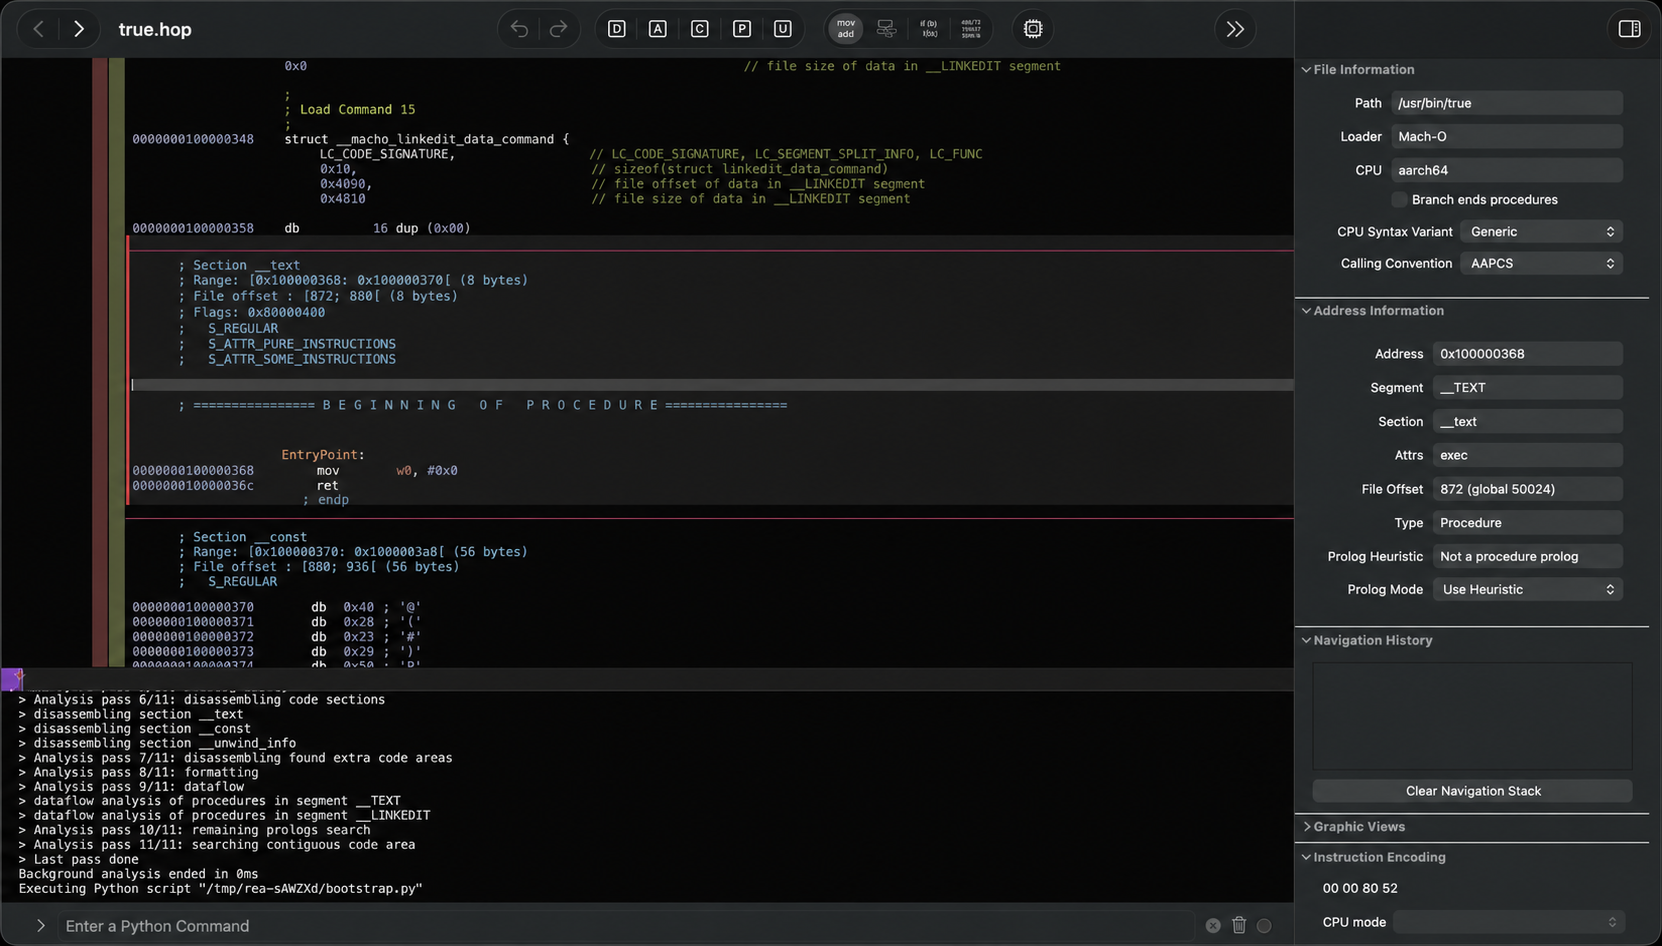
Illustration · not a resultFrom the morluto/rea README — shows the whole collection, not only this skill.source ↗
Reverse engineer native, managed, Electron/JavaScript, packaged, firmware, and browser targets with REA.
by morluto·MIT license·★ 316,276 Stars on the repo·GitHub ↗
npx degit morluto/rea/.agents/skills/reverse-engineer-anything#main ~/.claude/skills/reverse-engineer-anythingChecked ·commit main
Files of REA
Show the full text356 lines
REA
Use REA when a claim depends on a shipped binary or package, decompilation, passive application runtime evidence, or comparison with behavior not established by available source. For ordinary analysis of a complete source repository, use normal repository tools and do not run REA readiness or provider commands.
Connect only when needed
Installing this skill supplies instructions; it does not register the REA MCP server, install analysis engines, or add tools to an already-running agent.
If REA tools are available and their registration is not known to be stale, proceed directly to the target. Do not run diagnostics or setup before every investigation. Use the connected server's actual tool list and input schemas; a skill installed from repository main may describe capabilities absent from an older npm release. Keep complete inline Evidence when that server does not advertise retained references.
If tools are absent, a call is blocked by the client, or a required provider is unavailable, read connection and recovery. Diagnose the observed blocker, continue useful supported work, and resume the original task after repair. Client approval, shell PATH, registration and engine availability have different remedies; avoid repeating setup for all of them.
- Diagnose without changing REA or client configuration.
npxmay download the package and write to npm's cache. For Codex, runnpx -y rea-agents@latest doctor --client codex --json. Substitute the current supported client:claude_code,claude_desktop,codex,cursor,gemini_cli,windsurf,devin,opencode,antigravity,copilot_cli,commandcode,vscode,grok_build,omp, orgrok_bot.grok_bothas no local file registration: doctor reports the Grok Bot chat step, and setup does not writemcp.json. If the client is unknown, usedoctor --jsonand inspect its registration results before choosing a setup scope. - Distinguish the reason. Missing, malformed, or stale registration needs a scoped configuration repair. An aligned registration with no tools in the active session needs a restart/reconnection; doctor cannot prove that the current agent has connected. A missing provider affects only tasks requiring that provider: static JavaScript inspection needs neither Hopper nor Ghidra, and Android inspection has separate bring-your-own JADX/Java prerequisites.
- For a configuration repair, prepare the read-only plan:
npx -y rea-agents@latest setup --client codex --dry-run --json. Use the current client's ID, show its exact proposed paths, backups, and changes, and obtain approval before setup writes configuration or installs Hopper. Setup normally installs the matching bundled skill too; include that replacement in the reviewed plan. After approval, apply the same scope withnpx -y rea-agents@latest setup --client codex --yes. Add--install-hopperonly if that separate installation was needed and explicitly approved. - Restart/reconnect the affected agent. Verify that REA tools actually appear in the session, then resume the original investigation. If they remain absent, inspect the client's MCP launch error rather than repeating setup.
REA setup never installs or upgrades Node.js, npm, Homebrew, Java, Ghidra, IDA,
JADX, Kuna, Binwalk, or Unblob. Use existing prerequisites; do not install unrelated
software to repair
MCP registration. For an unsupported client, use manual stdio registration
with a version-pinned rea-agents package or continue through the CLI.
A concrete CLI fallback for an operator-supplied JavaScript tree or ASAR is:
npx -y rea-agents@latest analyze-javascript-application /absolute/path/to/app --json
No MCP registration or native engine is required. Read the returned Evidence,
graph, limitations, and unknowns with the same care as an MCP result; the CLI
returns the Evidence record directly. This fallback does not establish that
MCP is configured. Native CLI tasks still require their selected engine.
Prefer an existing rea CLI. When none is installed and REA package acquisition
is within the authorized scope, use npx -y rea-agents@latest in its place.
Configuration repair starts with a read-only setup plan; show paths, backups and
skill replacement before applying authorized changes. Preserve existing approval
and target-execution boundaries. REA setup never installs or upgrades unrelated
software, including Node.js, npm, Homebrew, Java, Ghidra, IDA, JADX, Kuna, Binwalk or Unblob.
Route the target first
Choose the first tool from the target the user supplied. Use open_binary for
active-target native or archive workflows; target-free tools take their own
explicit path or endpoint and do not need it.
ASAR or extracted JavaScript/Electron tree:
analyze_javascript_application.Archive/package member inventory (ZIP/APK/IPA/MSIX/AppX or DMG):
open_binarywith the supplied local path; useinspect_artifactwhen its graph and findings help answer the question.Android APK code, classes, methods, or incoming references:
inspect_android_package, then focused Android tools when advertised. Archive member inventory still uses the archive route above.Managed PE/CLI assembly:
inspect_managed_artifact.Firmware image:
inspect_firmware_regionswhen advertised. Useextract_firmwarewhen extraction is requested, with a caller-selected new absolute output directory. These tools use caller-supplied Binwalk/Unblob on Linux; see the firmware guide..NET NativeAOT PE/ELF: native Ghidra analysis. Native code can yield pseudocode; consult the NativeAOT workflow in
references/native-and-artifacts.mdfor optional metadata recovery and its supported host/layout boundary.User-owned browser page already open:
list_browser_targets.Browser action the agent must perform (click, type, navigate):
capture_browser_scenariowith declared actions. See runtime observation for connect/launch and the focused follow-up browser tools.Fiddler Everywhere traffic or a native
.sazcapture: read the Fiddler workflow. Inspect saved SAZ withinspect_web_network_captureandformat: "saz"; connect Everywhere's separate MCP server for live traffic.Retained HAR/SAZ/native mitmproxy/aioquic qlog capture:
inspect_web_network_capture. Select original record ordinals when useful; inspect producer fields and byte/number sidecars without fetching recorded URLs or claiming live attribution. See historical captures for the exact upstream profile and credential exclusions. Qlog support starts with aioquic 1.5.0 JSON 0.3; stream coverage and endpoint loss declarations do not recover bodies or establish network loss. Prefer detail summary, then kind qlog trace/stream pages; select one trace, stream ID and direction for contribution/range pages. Facts retain all-recorded-events-before-selection scope. Other qlog layouts and PCAP correlation are unsupported.User-owned Electron runtime already open:
list_electron_targets. Before an electron-main Inspector attempt, check packaged fuses withinspect_electron_fuses; disabledEnableNodeCliInspectArgumentsmeans the app ignores--inspect.Packet-field discovery:
inspect_packet_fieldssearches installed protocols and field names/types before choosing fields forinspect_packet_capture. Query/page the relevant records; registrations do not establish observed traffic.Recorded packet captures:
inspect_packet_capturewith selected TShark fields, display filters and decode-as rules. Requires Linux, util-linux prlimit andREA_TSHARK_COMMAND; see capture guide. Packet limits count input packets before filtering. Output defaults to 50 matching frames; usematch_offset/match_limitfor later pages, or explicit null limit for complete matching output. Preserve the source digest across pages. This does not perform live capture. For address/DNS/SNI/protocol summaries useinspect_pcap_capturewith MCP detail summary, then retained kind pcap pages. Requires Wireshark 4.x tshark and capinfos, with Linux prlimit or Windows Job Objects; see packet summaries. Select an exact DNS question for address pages; page exhaustion does not prove network completeness. This reads recordings and does not acquire traffic.Decoder discovery:
inspect_signal_decoderssearches installed decoder IDs or selected decoder help, including channels and options. Query and page the relevant details before choosing settings; this does not scan hardware.Recorded logic/signal traces:
decode_signal_recordingwith explicit decoder, channel and protocol settings. On Linux with util-linux prlimit, supply sigrok-cli 0.7.2 throughREA_SIGROK_COMMAND; see recording guide. Output defaults to 50 literal lines; select annotation classes and page withline_offset/line_limit, or explicit null for all remaining output. Window counts are display lines, not annotations or samples. Preserve source digests across pages. This reads existing files; it does not acquire hardware signals.Explicit local WebAssembly artifact:
inspect_wasm_artifact. Supply WABT 1.0.42 throughREA_WABT_BIN_DIRECTORY; retain exact byte/tool identity and decoded WAT. Select JavaScript glue and candidate paths explicitly and preserve URL/path ambiguity. No implicit fetch or target execution; WAT is not original source. See the WASM guide.Explicit local EVM bytecode carrier:
inspect_evm_interfacewith caller-selectedraworhexencoding. Preserve carrier/decoded digests and treat selectors, argument strings and mutability as inferred candidates; this performs no chain lookup or target execution. For the complete inferred interface without hex or duplicate stdout, discover support and selectdetail: "summary"; complete Evidence stays retained under its original identity. Use the returnedparent_evidence_idfor exact function orbytecode_hex/stdout/stderr pages. Candidate coverage does not establish interface completeness. See the EVM bytecode guide.Embedded Go compiler, module or build-setting metadata:
inspect_go_binarywith the explicit local file. This built-in target-free inspection requires no Go installation or disassembler. Preserve raw module bytes and source ranges; absent metadata does not prove a binary is not Go, and unparsed text records remain explicit. See the Go binary guide.Embedded cargo-auditable Rust dependency metadata:
inspect_rust_binarywith the explicit local ELF, PE, or thin Mach-O file. This built-in target-free inspection requires no Rust installation or disassembler. Preserve package order, dependency indices, and the section file range. A missing.dep-v0section is null metadata, not proof the binary has no dependencies. A rustc commit hash is an inference from a read-only/rustc/<40-hex>/path. See the Rust binary guide.Explicit local SQLite database snapshot:
inspect_sqlite_database. Inspect with Node.js 24.x >=24.15 or 26+ providing native SQLite limits. Read schema first (compact inventory by default), or select an exact ordinary table andcolumnswhen rows are needed. Defaults are selected-table schema and 20 rows; requestschema_scope: "database"for the complete stored schema. Preserve both database and existing sibling WAL identity; row samples report truncation and have unspecified order. Use a quiescent snapshot rather than assuming a live database/WAL pair was copied atomically. See the SQLite guide.Explicit Linux ELF file for offline layout, symbols, relocations or static mitigation evidence:
inspect_binary_layout. This target-free operation uses caller-supplied pwntools without opening a disassembler database. Preserve its raw locations and inference/coverage limits; see the offline binary guide.Supplied Linux x86-64 ELF core:
inspect_recorded_crash. Read every recorded thread, raw note and source-bound register without opening a live target. Historical PIDs do not select live processes. Requestinclude_debugger_contextonly when core-only mapping candidates help; see the recorded crash guide.PE resource type/name/language trees and static icon group references:
inspect_pe_resourceswith an explicit path. This portable operation requires no active target or engine; opaque payloads retain file ranges and SHA-256.Native executable, library, or analysis database:
open_binary, then use focused analysis tools directly; callbinary_overviewwhen metadata or inventory context is useful and available from the selected provider.
For an existing IDA MCP configuration, use open_binary with the original
input binary and provider_id: "ida"; do not pass an .idb or .i64 database.
The legacy attached profile binds the already-open GUI input by SHA-256 and
leaves its database open. The modern headless profile creates and closes an
owned private database without saving. Installation and registration reuse
mrexodia/ida-pro-mcp; see the
IDA provider guide.
Proceed directly to analyze_function, pseudocode, or function/string searches
after opening; IDA does not supply binary_overview. Consult session availability
when composing broader workflows. Modern direct callers and unsupported dossier
facets remain unknown; live IDA results are not replayed from snapshots.
With REA_KUNA_COMMAND configured, provider_id: "kuna" answers procedure
lists, lookups, pseudocode, assembly and analyze_function from Kuna's cached
whole-program export. Callers/callees use a separate body-free graph shared by
the session; xrefs returns exact-address incoming sites and filters forwarding
aliases. These queries and inventory lookups do not trigger a C export. Indirect
targets remain unknown and can make relationship coverage partial. Reference
caches expire on close; a fresh CLI process repeats the native reference walk.
Typed references, CFG, raw-memory tools and annotations remain unsupported. A cold first
answer can come from a single-function run (its limitations say so); assembly
waits for the export. For pseudocode and assembly, raw_result.source names the
cached .c/.asm file and byte span, which you may search directly instead of
calling per function. See the
Kuna provider guide.
If the user says only "my app" without a name, path, or target already selected for this task, ask which app before searching for artifacts. Paths in unrelated saved reports and nearby test fixtures do not select the user's target. Resolve an actual human-readable app name to one clear installed artifact when possible; ask when matches are ambiguous. Never choose an example app on the user's behalf.
In a target-free session, use open_binary to bind any archive/package or
native target whose analysis tool operates on the active target. Do not call an
unadvertised tool; inspect binary_session with {} and its
result.tool_availability for availability reasons and remediation. Expand each
group's names into entries, inheriting the inventory-level client requirements
unless the group overrides them. In its closed effect and annotation vocabularies,
listed flags are true and omitted known flags are false. The grouped name union
is the complete tool inventory; use tools/list for canonical tool schemas.
Provider candidate facts describe possible providers, while top-level session
capabilities describe the current route and analysis_provider_binding names the
selected provider. Do not treat those scopes as interchangeable.
Work summary-first
Start with the default result and use its inline Evidence and graph context.
For a JavaScript application or ELF layout whose size is unknown or large,
call analyze_javascript_application or inspect_binary_layout with
"detail": "summary", then inspect the retained parent_evidence_id with
inspect_analysis_view.
Page module identities and select the returned node_id before requesting an
item; a single file path can represent several graph roles. Do not repeat an
identical analysis or rejected call without a changed input or resolved blocker.
Recheck session state when a lifecycle change makes that status useful.
Make a focused follow-up only when the
returned result leaves a specific question unanswered.
If MCP reports resource_constraint with details.resource: "transport", call
inspect_analysis_view with its reported same-session Evidence reference for a
summary, one section/module, or a stable page. Use trace_application_feature
once a seed is known, or call export_evidence_bundle to write the complete
session to a selected path. The analysis remains complete in the ledger; avoid
repeating it merely to request the same oversized response. Complete CLI JSON
output also streams without a single MCP frame.
When the retained parent ID is unknown, use get_evidence_bundle with
detail: "summary" and exact filters for operation, target SHA-256,
analysis-profile digest or canonical procedure address. Select its returned
Evidence ID for the next view instead of requesting the complete bundle.
retention: "complete-record" means the whole record is stored; native
value-flow truncation and unknown metadata remain separate. For an exported
portable bundle, use rea inspect-evidence-bundle with JSON containing path,
detail: "summary" and the same filters. Reading that file still requires
validating its full contents within the local memory budget.
A client can also truncate a successful tool result without a REA transport error. Treat that preview as incomplete; use the retained parent ID for smaller views or export when the full record is needed. Do not parse the preview as canonical JSON or repeat the producer. For JavaScript, read the module-view and trace recipes before drilling into a large graph; a broad bidirectional trace can expand unrelated containment relationships even after summary analysis.
Every conclusion must distinguish observations, inferences, and unknowns. Cite Evidence IDs, preserve limitations and incomplete coverage, and never imply that static analysis observed execution. Runtime requests execute the declared target and lifecycle; do not broaden the target or action beyond those fields.
Within the user's requested investigation, call available analysis tools directly. REA does not require permission grants or per-call approval flags. The agent client can independently require approval. Follow the declared request scope and the host's actual access requirements; use the recovery guide for an observed client-policy rejection.
Plan broader investigations
For requests that span multiple features or subsystems, use a staged workflow:
- Turn the request into a checklist of questions and the evidence each answer needs. Resolve target identity and constraints from the conversation and workspace before asking for information again.
- Inspect the current REA session, artifact identity, saved analysis database, bookmarks, and prior evidence. Reuse matching state; do not open duplicate sessions or repeat identical analysis.
- Start with the smallest useful overview or inventory. Follow each question from its entry point through relevant data and state changes to its result. Batch related operations around a specific hypothesis, then expand only when the returned evidence leaves a concrete gap.
- Inspect relevant packaged resources and configuration alongside code when they affect the question. Use format-aware inventory and parsers; do not infer behavior from filenames, strings, or layout alone.
- Corroborate a conclusion with the evidence type it requires. Use runtime observation only when static evidence cannot answer the question and the required host runtime and OS access are available. For JavaScript behavior, run probes against the actual app through the available browser, Electron, or process capture workflow.
- Decompose work into independent questions. When parallel workers are available and the questions do not depend on one another, assign distinct scopes, point workers to existing evidence, and ask them to return sources, conclusions, and unresolved gaps. Otherwise, work sequentially.
- Keep a concise finding ledger linking each conclusion to Evidence IDs, confidence/evidence type, search boundary, and remaining unknowns. Update the shared index or investigation report so later passes can reuse results.
Before finishing, revisit the original checklist. Mark each question as answered, partially answered, or unresolved based on its evidence; keep bounded negative searches bounded, and do not describe a broad investigation as complete while required questions remain open.
Read only the relevant guide
- Native binaries, managed assemblies, archives, and extraction: references/native-and-artifacts.md
- ASARs, extracted JavaScript, feature tracing, and version comparison: references/javascript-applications.md
- Android APK declarations, classes, methods, and static references: references/android-applications.md
- Browser/Electron observation (passive and scenario) and static/runtime reconciliation: references/runtime-observation.md
- Evidence paging, comparisons, residual unknowns, and verification: references/evidence-workflows.md
Finish the task
Explain findings in plain language and tie them to returned evidence. When the
user asks to build something, use normal coding tools and separate observed
behavior from design choices. Close an opened native session with
close_binary when the investigation is complete.
| 1 | |
| 2 | name reverse-engineer-anything |
| 3 | description Reverse engineer native, managed, Electron/JavaScript, packaged, firmware, and browser targets with REA. Use shipped-artifact or requested runtime evidence to explain features, compare versions, decompile code, or guide a reconstruction. Skip REA for ordinary source-repository architecture analysis. |
| 4 | metadata |
| 5 | version "42" |
| 6 | |
| 7 | |
| 8 | # REA |
| 9 | |
| 10 | Use REA when a claim depends on a shipped binary or package, decompilation, |
| 11 | passive application runtime evidence, or comparison with |
| 12 | behavior not established by available source. For ordinary analysis of a |
| 13 | complete source repository, use normal repository tools and do not run REA |
| 14 | readiness or provider commands. |
| 15 | |
| 16 | ## Connect only when needed |
| 17 | |
| 18 | Installing this skill supplies instructions; it does not register the REA MCP |
| 19 | server, install analysis engines, or add tools to an already-running agent. |
| 20 | |
| 21 | If REA tools are available and their registration is not known to be stale, |
| 22 | proceed directly to the target. Do not run diagnostics or setup before every |
| 23 | investigation. Use the connected server's actual tool list and input schemas; |
| 24 | a skill installed from repository main may describe capabilities absent from |
| 25 | an older npm release. Keep complete inline Evidence when that server does not |
| 26 | advertise retained references. |
| 27 | |
| 28 | If tools are absent, a call is blocked by the client, or a required provider is |
| 29 | unavailable, read [connection and recovery]. |
| 30 | Diagnose the observed blocker, continue useful supported work, and resume the |
| 31 | original task after repair. Client approval, shell PATH, registration and engine |
| 32 | availability have different remedies; avoid repeating setup for all of them. |
| 33 | |
| 34 | Diagnose without changing REA or client configuration. `npx` may download |
| 35 | the package and write to npm's cache. For Codex, run |
| 36 | `npx -y rea-agents@latest doctor --client codex --json`. Substitute the current |
| 37 | supported client: `claude_code`, `claude_desktop`, `codex`, `cursor`, |
| 38 | `gemini_cli`, `windsurf`, `devin`, `opencode`, `antigravity`, `copilot_cli`, |
| 39 | `commandcode`, `vscode`, `grok_build`, `omp`, or `grok_bot`. `grok_bot` has no local |
| 40 | file registration: doctor reports the Grok Bot chat step, and setup does not |
| 41 | write `mcp.json`. If the client is unknown, use `doctor --json` and |
| 42 | inspect its registration results before choosing a setup scope. |
| 43 | Distinguish the reason. Missing, malformed, or stale registration needs a |
| 44 | scoped configuration repair. An aligned registration with no tools in the |
| 45 | active session needs a restart/reconnection; doctor cannot prove that the |
| 46 | current agent has connected. A missing provider affects only tasks requiring |
| 47 | that provider: static JavaScript inspection needs neither Hopper nor Ghidra, |
| 48 | and Android inspection has separate bring-your-own JADX/Java prerequisites. |
| 49 | For a configuration repair, prepare the read-only plan: |
| 50 | `npx -y rea-agents@latest setup --client codex --dry-run --json`. |
| 51 | Use the current client's ID, show its exact proposed paths, backups, and |
| 52 | changes, and obtain approval before setup writes configuration or installs |
| 53 | Hopper. Setup normally installs the matching bundled skill too; include that |
| 54 | replacement in the reviewed plan. After approval, apply the same scope with |
| 55 | `npx -y rea-agents@latest setup --client codex --yes`. Add `--install-hopper` |
| 56 | only if that separate installation was needed and explicitly approved. |
| 57 | Restart/reconnect the affected agent. Verify that REA tools actually appear |
| 58 | in the session, then resume the original investigation. If they remain |
| 59 | absent, inspect the client's MCP launch error rather than repeating setup. |
| 60 | |
| 61 | REA setup never installs or upgrades Node.js, npm, Homebrew, Java, Ghidra, IDA, |
| 62 | JADX, Kuna, Binwalk, or Unblob. Use existing prerequisites; do not install unrelated |
| 63 | software to repair |
| 64 | MCP registration. For an unsupported client, use manual stdio registration |
| 65 | with a version-pinned `rea-agents` package or continue through the CLI. |
| 66 | |
| 67 | A concrete CLI fallback for an operator-supplied JavaScript tree or ASAR is: |
| 68 | |
| 69 | |
| 70 | npx -y rea-agents@latest analyze-javascript-application /absolute/path/to/app --json |
| 71 | |
| 72 | |
| 73 | No MCP registration or native engine is required. Read the returned Evidence, |
| 74 | graph, limitations, and unknowns with the same care as an MCP result; the CLI |
| 75 | returns the Evidence record directly. This fallback does not establish that |
| 76 | MCP is configured. Native CLI tasks still require their selected engine. |
| 77 | Prefer an existing `rea` CLI. When none is installed and REA package acquisition |
| 78 | is within the authorized scope, use `npx -y rea-agents@latest` in its place. |
| 79 | Configuration repair starts with a read-only setup plan; show paths, backups and |
| 80 | skill replacement before applying authorized changes. Preserve existing approval |
| 81 | and target-execution boundaries. REA setup never installs or upgrades unrelated |
| 82 | software, including Node.js, npm, Homebrew, Java, Ghidra, IDA, JADX, Kuna, Binwalk or Unblob. |
| 83 | |
| 84 | ## Route the target first |
| 85 | |
| 86 | Choose the first tool from the target the user supplied. Use `open_binary` for |
| 87 | active-target native or archive workflows; target-free tools take their own |
| 88 | explicit path or endpoint and do not need it. |
| 89 | |
| 90 | ASAR or extracted JavaScript/Electron tree: |
| 91 | `analyze_javascript_application`. |
| 92 | Archive/package member inventory (ZIP/APK/IPA/MSIX/AppX or DMG): |
| 93 | `open_binary` with the supplied local path; use `inspect_artifact` when its |
| 94 | graph and findings help answer the question. |
| 95 | Android APK code, classes, methods, or incoming references: |
| 96 | `inspect_android_package`, then focused Android tools when advertised. |
| 97 | Archive member inventory still uses the archive route above. |
| 98 | Managed PE/CLI assembly: `inspect_managed_artifact`. |
| 99 | Firmware image: `inspect_firmware_regions` when advertised. Use |
| 100 | `extract_firmware` when extraction is requested, with a caller-selected new |
| 101 | absolute output directory. These tools use caller-supplied Binwalk/Unblob on |
| 102 | Linux; see the [firmware guide]. |
| 103 | .NET NativeAOT PE/ELF: native Ghidra analysis. Native code can yield pseudocode; |
| 104 | consult the NativeAOT workflow in `references/native-and-artifacts.md` for |
| 105 | optional metadata recovery and its supported host/layout boundary. |
| 106 | User-owned browser page already open: `list_browser_targets`. |
| 107 | Browser action the agent must perform (click, type, navigate): |
| 108 | `capture_browser_scenario` with declared actions. See |
| 109 | [runtime observation] for connect/launch |
| 110 | and the focused follow-up browser tools. |
| 111 | Fiddler Everywhere traffic or a native `.saz` capture: read the |
| 112 | [Fiddler workflow]. |
| 113 | Inspect saved SAZ with `inspect_web_network_capture` and `format: "saz"`; |
| 114 | connect Everywhere's separate MCP server for live traffic. |
| 115 | Retained HAR/SAZ/native mitmproxy/aioquic qlog capture: `inspect_web_network_capture`. Select |
| 116 | original record ordinals when useful; inspect producer fields and byte/number |
| 117 | sidecars without fetching recorded URLs or claiming live attribution. See |
| 118 | [historical captures] for the exact upstream |
| 119 | profile and credential exclusions. Qlog support starts with aioquic 1.5.0 |
| 120 | JSON 0.3; stream coverage and endpoint loss declarations do not recover bodies |
| 121 | or establish network loss. Prefer detail summary, then kind qlog trace/stream |
| 122 | pages; select one trace, stream ID and direction for contribution/range pages. |
| 123 | Facts retain all-recorded-events-before-selection scope. Other qlog layouts |
| 124 | and PCAP correlation are unsupported. |
| 125 | User-owned Electron runtime already open: `list_electron_targets`. Before an electron-main Inspector attempt, check packaged fuses with `inspect_electron_fuses`; disabled `EnableNodeCliInspectArguments` means the app ignores `--inspect`. |
| 126 | Packet-field discovery: `inspect_packet_fields` searches installed protocols |
| 127 | and field names/types before choosing fields for `inspect_packet_capture`. |
| 128 | Query/page the relevant records; registrations do not establish observed traffic. |
| 129 | Recorded packet captures: `inspect_packet_capture` with selected TShark fields, |
| 130 | display filters and decode-as rules. Requires Linux, util-linux prlimit and `REA_TSHARK_COMMAND`; see |
| 131 | [capture guide]. |
| 132 | Packet limits count input packets before filtering. Output defaults to 50 matching |
| 133 | frames; use `match_offset` / `match_limit` for later pages, or explicit null |
| 134 | limit for complete matching output. Preserve the source digest across pages. |
| 135 | This does not perform live capture. |
| 136 | For address/DNS/SNI/protocol summaries use `inspect_pcap_capture` with MCP |
| 137 | detail summary, then retained kind pcap pages. Requires Wireshark 4.x tshark |
| 138 | and capinfos, with Linux prlimit or Windows Job Objects; see |
| 139 | [packet summaries]. |
| 140 | Select an exact DNS question for address pages; page exhaustion does not prove |
| 141 | network completeness. This reads recordings and does not acquire traffic. |
| 142 | Decoder discovery: `inspect_signal_decoders` searches installed decoder IDs |
| 143 | or selected decoder help, including channels and options. Query and page the |
| 144 | relevant details before choosing settings; this does not scan hardware. |
| 145 | Recorded logic/signal traces: `decode_signal_recording` with explicit decoder, |
| 146 | channel and protocol settings. On Linux with util-linux prlimit, supply sigrok-cli 0.7.2 through |
| 147 | `REA_SIGROK_COMMAND`; see [recording guide]. |
| 148 | Output defaults to 50 literal lines; select annotation classes and page with |
| 149 | `line_offset` / `line_limit`, or explicit null for all remaining output. |
| 150 | Window counts are display lines, not annotations or samples. Preserve source digests across pages. |
| 151 | This reads existing files; it does not acquire hardware signals. |
| 152 | Explicit local WebAssembly artifact: `inspect_wasm_artifact`. Supply WABT 1.0.42 |
| 153 | through `REA_WABT_BIN_DIRECTORY`; retain exact byte/tool identity and decoded WAT. |
| 154 | Select JavaScript glue and candidate paths explicitly and preserve URL/path |
| 155 | ambiguity. No implicit fetch or target execution; WAT is not original source. |
| 156 | See the [WASM guide]. |
| 157 | Explicit local EVM bytecode carrier: `inspect_evm_interface` with caller-selected |
| 158 | `raw` or `hex` encoding. Preserve carrier/decoded digests and treat selectors, |
| 159 | argument strings and mutability as inferred candidates; this performs no chain |
| 160 | lookup or target execution. For the complete inferred interface without hex or |
| 161 | duplicate stdout, discover support and select `detail: "summary"`; complete |
| 162 | Evidence stays retained under its original identity. Use the returned |
| 163 | `parent_evidence_id` for exact function or `bytecode_hex`/stdout/stderr pages. |
| 164 | Candidate coverage does not establish interface completeness. See the |
| 165 | [EVM bytecode guide]. |
| 166 | Embedded Go compiler, module or build-setting metadata: `inspect_go_binary` |
| 167 | with the explicit local file. This built-in target-free inspection requires no |
| 168 | Go installation or disassembler. Preserve raw module bytes and source ranges; |
| 169 | absent metadata does not prove a binary is not Go, and unparsed text records |
| 170 | remain explicit. See the |
| 171 | [Go binary guide]. |
| 172 | Embedded cargo-auditable Rust dependency metadata: `inspect_rust_binary` |
| 173 | with the explicit local ELF, PE, or thin Mach-O file. This built-in |
| 174 | target-free inspection requires no Rust installation or disassembler. Preserve |
| 175 | package order, dependency indices, and the section file range. A missing |
| 176 | `.dep-v0` section is null metadata, not proof the binary has no dependencies. |
| 177 | A rustc commit hash is an inference from a read-only `/rustc/<40-hex>/` path. |
| 178 | See the |
| 179 | [Rust binary guide]. |
| 180 | |
| 181 | Explicit local SQLite database snapshot: `inspect_sqlite_database`. Inspect |
| 182 | with Node.js 24.x >=24.15 or 26+ providing native SQLite limits. Read schema |
| 183 | first (compact inventory by default), or select an exact ordinary table |
| 184 | and `columns` when rows are needed. Defaults are selected-table schema and |
| 185 | 20 rows; request `schema_scope: "database"` for the complete stored schema. Preserve both database and existing sibling WAL identity; row samples |
| 186 | report truncation and have unspecified order. Use a quiescent snapshot rather |
| 187 | than assuming a live database/WAL pair was copied atomically. See the |
| 188 | [SQLite guide]. |
| 189 | Explicit Linux ELF file for offline layout, symbols, relocations or static |
| 190 | mitigation evidence: `inspect_binary_layout`. This target-free operation uses |
| 191 | caller-supplied pwntools without opening a disassembler database. Preserve its |
| 192 | raw locations and inference/coverage limits; see the |
| 193 | [offline binary guide]. |
| 194 | Supplied Linux x86-64 ELF core: `inspect_recorded_crash`. Read every recorded |
| 195 | thread, raw note and source-bound register without opening a live target. |
| 196 | Historical PIDs do not select live processes. Request `include_debugger_context` |
| 197 | only when core-only mapping candidates help; see the |
| 198 | [recorded crash guide]. |
| 199 | PE resource type/name/language trees and static icon group references: |
| 200 | `inspect_pe_resources` with an explicit path. This portable operation requires |
| 201 | no active target or engine; opaque payloads retain file ranges and SHA-256. |
| 202 | Native executable, library, or analysis database: `open_binary`, then |
| 203 | use focused analysis tools directly; call `binary_overview` when metadata or |
| 204 | inventory context is useful and available from the selected provider. |
| 205 | |
| 206 | For an existing IDA MCP configuration, use `open_binary` with the original |
| 207 | input binary and `provider_id: "ida"`; do not pass an `.idb` or `.i64` database. |
| 208 | The legacy attached profile binds the already-open GUI input by SHA-256 and |
| 209 | leaves its database open. The modern headless profile creates and closes an |
| 210 | owned private database without saving. Installation and registration reuse |
| 211 | [mrexodia/ida-pro-mcp]; see the |
| 212 | [IDA provider guide]. |
| 213 | Proceed directly to `analyze_function`, pseudocode, or function/string searches |
| 214 | after opening; IDA does not supply `binary_overview`. Consult session availability |
| 215 | when composing broader workflows. Modern direct callers and unsupported dossier |
| 216 | facets remain unknown; live IDA results are not replayed from snapshots. |
| 217 | |
| 218 | With `REA_KUNA_COMMAND` configured, `provider_id: "kuna"` answers procedure |
| 219 | lists, lookups, pseudocode, assembly and `analyze_function` from Kuna's cached |
| 220 | whole-program export. Callers/callees use a separate body-free graph shared by |
| 221 | the session; `xrefs` returns exact-address incoming sites and filters forwarding |
| 222 | aliases. These queries and inventory lookups do not trigger a C export. Indirect |
| 223 | targets remain unknown and can make relationship coverage partial. Reference |
| 224 | caches expire on close; a fresh CLI process repeats the native reference walk. |
| 225 | Typed references, CFG, raw-memory tools and annotations remain unsupported. A cold first |
| 226 | answer can come from a single-function run (its limitations say so); assembly |
| 227 | waits for the export. For pseudocode and assembly, `raw_result.source` names the |
| 228 | cached `.c`/`.asm` file and byte span, which you may search directly instead of |
| 229 | calling per function. See the |
| 230 | [Kuna provider guide]. |
| 231 | |
| 232 | If the user says only "my app" without a name, path, or target already selected |
| 233 | for this task, ask which app before searching for artifacts. Paths in unrelated |
| 234 | saved reports and nearby test fixtures do not select the user's target. Resolve |
| 235 | an actual human-readable app name to one clear installed artifact when possible; |
| 236 | ask when matches are ambiguous. Never choose an example app on the user's behalf. |
| 237 | |
| 238 | In a target-free session, use `open_binary` to bind any archive/package or |
| 239 | native target whose analysis tool operates on the active target. Do not call an |
| 240 | unadvertised tool; inspect `binary_session` with `{}` and its |
| 241 | `result.tool_availability` for availability reasons and remediation. Expand each |
| 242 | group's `names` into entries, inheriting the inventory-level client requirements |
| 243 | unless the group overrides them. In its closed effect and annotation vocabularies, |
| 244 | listed flags are true and omitted known flags are false. The grouped name union |
| 245 | is the complete tool inventory; use `tools/list` for canonical tool schemas. |
| 246 | Provider candidate facts describe possible providers, while top-level session |
| 247 | capabilities describe the current route and `analysis_provider_binding` names the |
| 248 | selected provider. Do not treat those scopes as interchangeable. |
| 249 | |
| 250 | ## Work summary-first |
| 251 | |
| 252 | Start with the default result and use its inline Evidence and graph context. |
| 253 | For a JavaScript application or ELF layout whose size is unknown or large, |
| 254 | call `analyze_javascript_application` or `inspect_binary_layout` with |
| 255 | `"detail": "summary"`, then inspect the retained `parent_evidence_id` with |
| 256 | `inspect_analysis_view`. |
| 257 | Page module identities and select the returned `node_id` before requesting an |
| 258 | item; a single file path can represent several graph roles. Do not repeat an |
| 259 | identical analysis or rejected call without a changed input or resolved blocker. |
| 260 | Recheck session state when a lifecycle change makes that status useful. |
| 261 | Make a focused follow-up only when the |
| 262 | returned result leaves a specific question unanswered. |
| 263 | |
| 264 | If MCP reports `resource_constraint` with `details.resource: "transport"`, call |
| 265 | `inspect_analysis_view` with its reported same-session Evidence reference for a |
| 266 | summary, one section/module, or a stable page. Use `trace_application_feature` |
| 267 | once a seed is known, or call `export_evidence_bundle` to write the complete |
| 268 | session to a selected path. The analysis remains complete in the ledger; avoid |
| 269 | repeating it merely to request the same oversized response. Complete CLI JSON |
| 270 | output also streams without a single MCP frame. |
| 271 | |
| 272 | When the retained parent ID is unknown, use `get_evidence_bundle` with |
| 273 | `detail: "summary"` and exact filters for operation, target SHA-256, |
| 274 | analysis-profile digest or canonical procedure address. Select its returned |
| 275 | Evidence ID for the next view instead of requesting the complete bundle. |
| 276 | `retention: "complete-record"` means the whole record is stored; native |
| 277 | value-flow truncation and unknown metadata remain separate. For an exported |
| 278 | portable bundle, use `rea inspect-evidence-bundle` with JSON containing `path`, |
| 279 | `detail: "summary"` and the same `filters`. Reading that file still requires |
| 280 | validating its full contents within the local memory budget. |
| 281 | |
| 282 | A client can also truncate a successful tool result without a REA transport |
| 283 | error. Treat that preview as incomplete; use the retained parent ID for smaller |
| 284 | views or export when the full record is needed. Do not parse the preview as |
| 285 | canonical JSON or repeat the producer. For JavaScript, read the |
| 286 | [module-view and trace recipes] before |
| 287 | drilling into a large graph; a broad bidirectional trace can expand unrelated |
| 288 | containment relationships even after summary analysis. |
| 289 | |
| 290 | Every conclusion must distinguish observations, inferences, and unknowns. Cite |
| 291 | Evidence IDs, preserve limitations and incomplete coverage, and never imply |
| 292 | that static analysis observed execution. Runtime requests execute the declared |
| 293 | target and lifecycle; do not broaden the target or action beyond those fields. |
| 294 | |
| 295 | Within the user's requested investigation, call available analysis tools |
| 296 | directly. REA does not require permission grants or per-call approval flags. |
| 297 | The agent client can independently require approval. Follow the declared request |
| 298 | scope and the host's actual access requirements; use the recovery guide for an |
| 299 | observed client-policy rejection. |
| 300 | |
| 301 | ## Plan broader investigations |
| 302 | |
| 303 | For requests that span multiple features or subsystems, use a staged workflow: |
| 304 | |
| 305 | Turn the request into a checklist of questions and the evidence each answer |
| 306 | needs. Resolve target identity and constraints from the conversation and |
| 307 | workspace before asking for information again. |
| 308 | Inspect the current REA session, artifact identity, saved analysis database, |
| 309 | bookmarks, and prior evidence. Reuse matching state; do not open duplicate |
| 310 | sessions or repeat identical analysis. |
| 311 | Start with the smallest useful overview or inventory. Follow each question |
| 312 | from its entry point through relevant data and state changes to its result. |
| 313 | Batch related operations around a specific hypothesis, then expand only when |
| 314 | the returned evidence leaves a concrete gap. |
| 315 | Inspect relevant packaged resources and configuration alongside code when |
| 316 | they affect the question. Use format-aware inventory and parsers; do not |
| 317 | infer behavior from filenames, strings, or layout alone. |
| 318 | Corroborate a conclusion with the evidence type it requires. Use runtime |
| 319 | observation only when static evidence cannot answer the question and the |
| 320 | required host runtime and OS access are available. For JavaScript behavior, |
| 321 | run probes against the actual app through the available browser, Electron, |
| 322 | or process capture workflow. |
| 323 | Decompose work into independent questions. When parallel workers are |
| 324 | available and the questions do not depend on one another, assign distinct |
| 325 | scopes, point workers to existing evidence, and ask them to return sources, |
| 326 | conclusions, and unresolved gaps. Otherwise, work sequentially. |
| 327 | Keep a concise finding ledger linking each conclusion to Evidence IDs, |
| 328 | confidence/evidence type, search boundary, and remaining unknowns. Update |
| 329 | the shared index or investigation report so later passes can reuse results. |
| 330 | |
| 331 | Before finishing, revisit the original checklist. Mark each question as |
| 332 | answered, partially answered, or unresolved based on its evidence; keep |
| 333 | bounded negative searches bounded, and do not describe a broad investigation |
| 334 | as complete while required questions remain open. |
| 335 | |
| 336 | ## Read only the relevant guide |
| 337 | |
| 338 | Native binaries, managed assemblies, archives, and extraction: |
| 339 | [references/native-and-artifacts.md] |
| 340 | ASARs, extracted JavaScript, feature tracing, and version comparison: |
| 341 | [references/javascript-applications.md] |
| 342 | Android APK declarations, classes, methods, and static references: |
| 343 | [references/android-applications.md] |
| 344 | Browser/Electron observation (passive and scenario) and static/runtime |
| 345 | reconciliation: |
| 346 | [references/runtime-observation.md] |
| 347 | Evidence paging, comparisons, residual unknowns, and verification: |
| 348 | [references/evidence-workflows.md] |
| 349 | |
| 350 | ## Finish the task |
| 351 | |
| 352 | Explain findings in plain language and tie them to returned evidence. When the |
| 353 | user asks to build something, use normal coding tools and separate observed |
| 354 | behavior from design choices. Close an opened native session with |
| 355 | `close_binary` when the investigation is complete. |
| 356 |
Discussion
Browse more free Claude skills.